Executive Snapshot
Agentic AI has moved quickly from concept to enterprise agenda, but supply-chain operations impose a harder test than a demonstration. An agent must work inside real systems, use current operational context, operate within explicit decision rights, expose what it did, and improve a measurable business cycle.
The DataRobot and Supply Chain Now on-demand session makes the production distinction concrete. Its examples span supplier and tariff risk, plant operations, and aftermarket service, including a tariff signal tied to $2.5 billion in revenue risk that was addressed in 72 hours rather than weeks, with human sign-off retained. [1]
For supply-chain, manufacturing, operations, IT, and transformation leaders, production readiness should therefore be evaluated as an operating capability, not as a feature checklist.
Key Industry Updates: The Scaling Gap Is Operational
Supply Chain Now's June 2026 session on scaling agentic AI focuses on the operating discipline required to move from pilots to enterprise performance. Its framing is consistent with the campaign's central production question: not whether an agent can perform a task in isolation, but whether the surrounding workflow, controls, systems, and people are ready to support repeatable operational use. [2]
DataRobot's 2026 Unmet AI Needs Survey adds another production signal. Based on 413 AI practitioners and leaders across highly regulated industries, DataRobot reports that 94% of organizations experience Day 2 operations issues after deploying agentic AI, while cost control, infrastructure, security, vendor lock-in, and agent governance remain material barriers. [3]
These findings reinforce the same point: the hard part begins after a model works. Production depends on context, integration, authority, exception handling, observability, and operational ownership.
Test 1: Can the Agent See the Right Context?
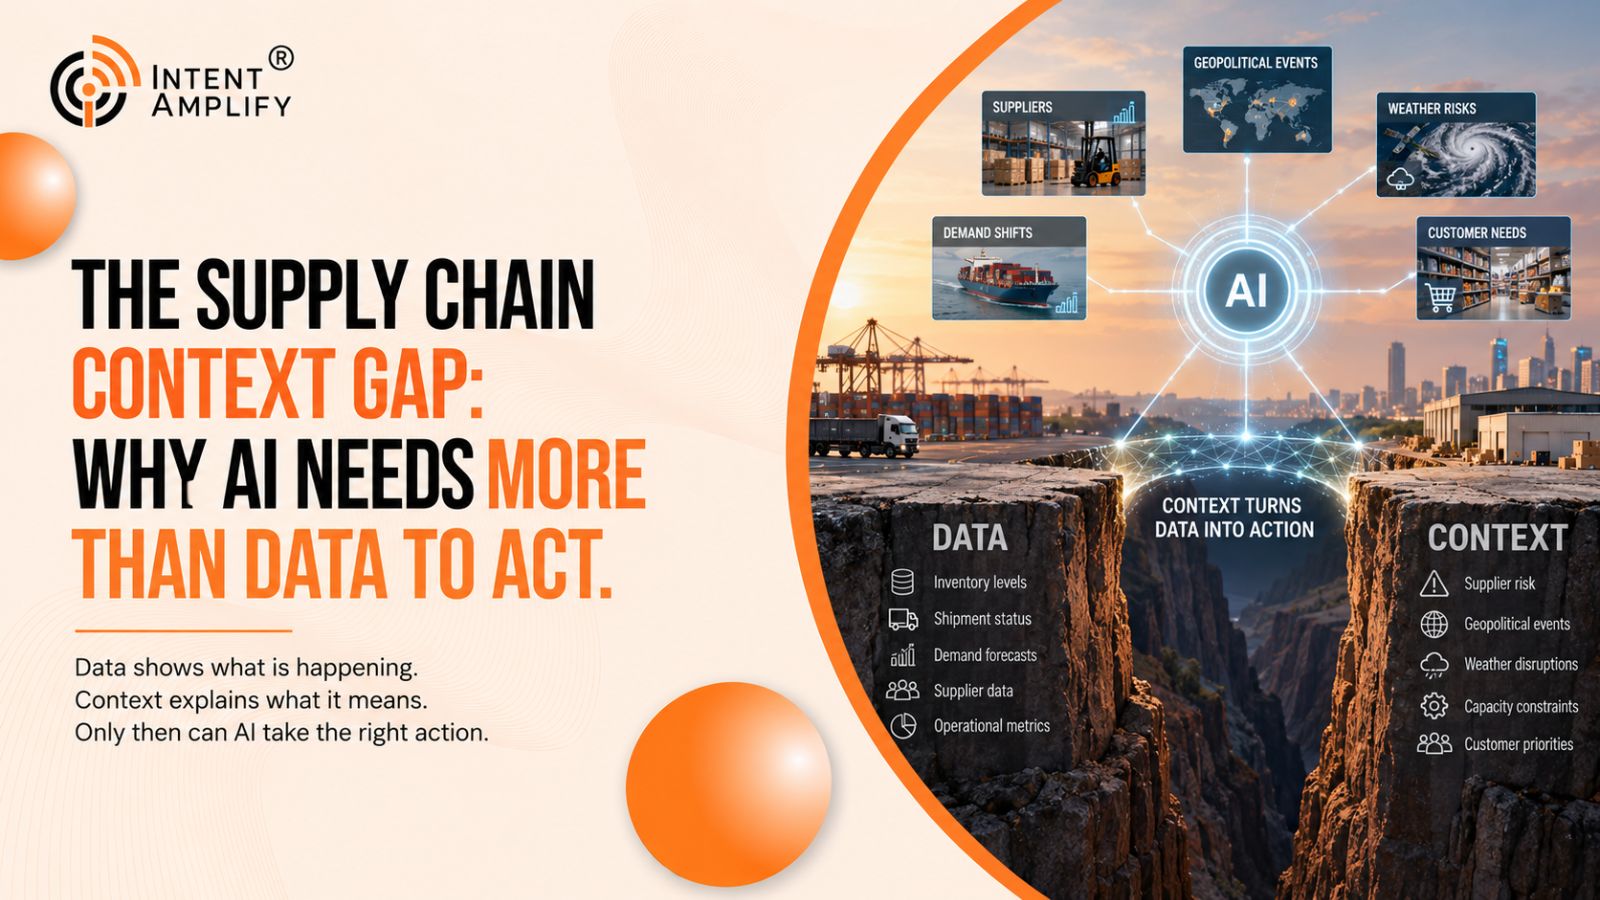
A useful supply-chain agent needs decision-specific context. Depending on the workflow, that can include supplier dependencies, tariff exposure, demand, inventory, plant constraints, service history, commercial rules, and data provenance.
The agent should also know which source is authoritative and how fresh that source must be. If required evidence is missing or conflicting, the workflow should expose the gap rather than silently infer operational truth.
Test 2: Can It Work Across Systems Without Creating a New Silo?
Supply-chain decisions rarely live in one application. A disruption may require supplier records, planning assumptions, inventory positions, logistics constraints, plant capacity, warranty history, and commercial terms.
Production value appears when the agent connects the minimum systems required to close a defined decision loop. DataRobot's 2026 enterprise infrastructure announcements emphasize deployment and governance across cloud, hybrid, on-premises, and other environments, reflecting the need to fit agentic workflows into existing enterprise architecture rather than forcing a new isolated stack. [4]
Test 3: Are Decision Rights Explicit?
Read, analyze, recommend, approve, execute, and verify are different permissions. Combining them too early can create unnecessary risk. Making every step manual preserves the latency the program is supposed to reduce.
Production design should assign authority according to consequence, reversibility, policy, and confidence in the evidence. High-impact decisions can still move faster while preserving accountable human review.
Test 4: Is the Agent Observable?
Business owners need more than technical logs. They need a readable chain showing the trigger, evidence consulted, assumptions made, tools used, policy checks, recommendation, approval, action, and verified result.
This is especially important as agents move closer to physical operations. DataRobot's collaboration with Chevron, announced in June 2026, applies agentic AI to autonomous inspection operations while working within established operational standards, illustrating why operational controls and traceability matter when AI-supported decisions affect real-world activity. [5]
Test 5: Does the Workflow Improve a Business Cycle?
Attach the agent to a measurable cycle such as supplier-risk response, shortage resolution, production recovery, warranty triage, or dispatch. Establish the baseline before deployment: elapsed time, handoffs, evidence sources, exception rates, and reopened decisions.
Then measure the same cycle after deployment. Usage can show adoption, but it does not prove operational value. The relevant evidence is whether the workflow helps teams reach a defensible outcome faster and with clearer accountability.
What These Five Tests Change in Practice
Taken together, the five tests shift the evaluation of agentic AI away from a narrow model-performance question. The operating question is whether the workflow can repeatedly assemble trustworthy context, move across the necessary systems, respect decision rights, show its work, and improve a business cycle that leaders already care about. A strong pilot can demonstrate one or two of those capabilities. Production readiness requires them to work together when conditions are less controlled.
That distinction is especially relevant in supply chain because the trigger and the decision are often separated by organizational boundaries. A supplier-risk signal may begin with procurement data but quickly require inventory, planning, logistics, plant, finance, and customer context. A plant issue may require maintenance evidence, production constraints, service commitments, and escalation rules. An aftermarket case can cross warranty history, parts availability, dispatch, and customer-service systems. The agent should not be judged only by whether it generates a plausible recommendation. It should be judged by whether the recommendation is grounded in the right evidence and can move through the authorized workflow.
Use the Tests as a Pre-Production Gate
Before moving an agentic workflow into production, teams can turn the five tests into a practical gate. First, name the decision the workflow is meant to improve and the measurable delay or friction in the current process. Then identify the authoritative evidence required to make that decision. Next, map the minimum systems the workflow must read from or act through. Define which actions the agent may take independently, which require approval, and which should always escalate.
The same gate should specify what must be observable after every run. A business owner should be able to understand what triggered the workflow, which evidence was used, where information was missing, what recommendation was produced, who approved it, what action followed, and whether the expected outcome was verified. If those questions cannot be answered consistently, the organization may have a useful prototype but not yet a production-grade operating capability.
This approach also helps prevent premature expansion. Instead of adding more agents, more integrations, or broader permissions simply because the technology allows it, leaders can expand only after a bounded workflow demonstrates that its context, controls, and measurement hold up under normal exceptions. That creates a clearer path from one successful decision loop to a portfolio of governed agentic workflows.
What to Measure Beyond Agent Activity
Production measurement should separate activity from business-cycle improvement. The number of agent runs, prompts, recommendations, or users can indicate adoption, but those measures do not show whether the underlying operating problem has improved. For a supplier-risk workflow, the useful baseline may be time from signal to validated exposure, recommendation, approval, and response. For a plant workflow, it may be time from detected constraint to an approved recovery action. For aftermarket service, it may be time from issue identification to an authorized dispatch or warranty decision.
Teams should measure control quality at the same time. Useful indicators include how often required evidence is unavailable, how often systems return conflicting records, how often a recommendation is escalated or changed by a human, and whether executed actions can be reconstructed from the record. The goal is not to eliminate human involvement. It is to understand whether the workflow reduces avoidable delay while keeping accountable people in the decisions that require them.
A useful final check is to run the workflow against failure conditions before declaring it ready. Teams should test stale or missing data, an unavailable source system, conflicting records, an action outside the agent’s permission, and a recommendation that requires escalation. The expected behavior should be defined in advance: stop, request evidence, route to a human, or continue within a narrower permitted path. Production confidence comes from predictable behavior when the ideal path breaks.
Ownership should be equally explicit. Business teams own the decision and its outcome; technology teams own the reliability of the enabling environment; governance and security functions define applicable controls; and named approvers remain accountable for consequential actions. When ownership is distributed but not defined, an agent can make information move faster while the decision itself still waits.
For executives, this provides a straightforward scaling principle: expand agentic AI only when the next workflow has a clear decision, credible evidence, bounded authority, observable execution, and a measurable operating baseline. That discipline keeps the program focused on decisions that matter rather than on the number of agents deployed. It also makes comparisons between use cases more useful because leaders can evaluate each workflow against the same production-readiness questions.
Conclusion: Production Grade Means the Workflow Survives Reality
Production-grade agentic AI is an operating-system question as much as a model question. Context, integration, authority, exception behavior, observability, and business-cycle improvement must be designed together.
The strongest proof is not that an agent can complete a demo. It is that the workflow continues to behave safely and usefully when data is incomplete, systems are imperfect, consequences are material, and accountable people still own the decision.
Watch Now
$2.5B in 72 Hours: What Agentic AI Looks Like When It Actually Works
References
1. DataRobot (2026) $2.5B in 72 Hours: What Agentic AI Looks Like When It Actually Works. Available at: https://www.datarobot.com/webinars/2-5b-in-72-hours-what-agentic-ai-looks-like-when-it-actually-works/
2. Supply Chain Now (June 11, 2026) From AI Pilots to Performance: How Supply Chain Leaders Are Scaling Agentic AI. Available at: https://supplychainnow.com/ai-pilots-to-performance-how-supply-chain-leaders-scaling-agentic-ai/
3. DataRobot (2026) The Unmet AI Needs Survey 2026. Available at: https://www.datarobot.com/resources/unmet-ai-needs-survey-2026/
4. DataRobot (June 24, 2026) A 3X Leader for the Agentic Era: DataRobot Named a Leader Again in the Gartner Magic Quadrant for Data Science and Machine Learning Platforms. Available at: https://www.datarobot.com/newsroom/press/a-3x-leader-for-the-agentic-era-datarobot-named-a-leader-again-in-the-gartner-magic-quadrant-for-data-science-and-machine-learning-platforms/
5. DataRobot (September 24, 2026) The Unsexy AI: Why Your Forklift Matters More Than Your Chatbot. Available at: https://www.datarobot.com/blog/the-unsexy-ai-why-your-forklift-matters-more-than-your-chatbot/